
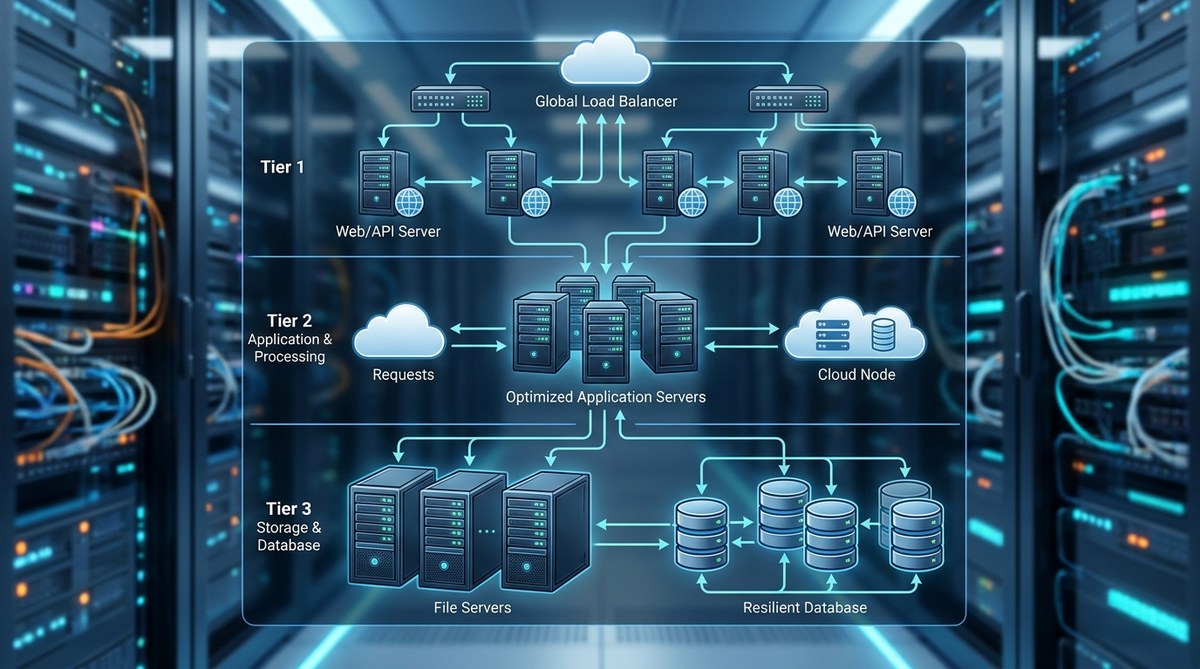
Building a file hosting system that stays online when traffic spikes and hardware fails is a challenge every backend engineer faces. A single storage layer works fine for a prototype, but as your SaaS platform grows, that single point of failure becomes a liability. A multi-tier file hosting architecture solves this by distributing the load across several specialized layers. Each tier handles a specific job: caching hot files, storing originals, serving content globally, or managing metadata. When one tier stumbles, the others keep your users downloading and uploading without interruption. This guide walks through the design decisions, trade offs, and concrete steps to build a system that delivers maximum uptime for your users in 2026.
A multi-tier file hosting architecture separates storage, caching, metadata, and delivery into independent layers. This isolation prevents a single hardware failure or traffic surge from taking down the entire system. By combining object storage for durability, an in-memory cache for hot files, a CDN for global reach, and a replicated database for metadata, you achieve both high performance and resilience. Each tier scales independently, making the architecture future proof as your user base grows.
Why a Single Storage Tier Is a Risk
A single S3 bucket or a single NFS volume feels simple to manage. You write files to one place, read from the same place, and call it a day. But that simplicity hides real risks. If the storage provider has an outage in one region, your entire upload and download pipeline stops. If a misconfigured application accidentally deletes files, there is no second layer to catch the mistake. And when a popular file goes viral, the same storage backend that handles cold archival data also has to serve that traffic. Latency spikes, timeouts increase, and users start seeing errors.
A multi-tier architecture spreads these risks across independent systems. The hot tier handles real time reads and writes with low latency. The warm tier stores files that are accessed less often but still need fast retrieval. The cold tier archives old data on cheap storage. Each tier has its own scaling rules, redundancy strategy, and failure mode. When one tier degrades, the others continue operating.
The Core Tiers of a Resilient File Hosting System
A practical multi-tier file hosting architecture uses four main layers. Each layer solves a specific problem and can be swapped or upgraded without touching the others.
Tier 1: Edge Cache and CDN
The edge cache is the first stop for any read request. A content delivery network (CDN) like CloudFront, Fastly, or Cloudflare stores copies of frequently accessed files in points of presence around the world. When a user in Los Angeles requests a file, the CDN serves it from a nearby edge node instead of routing the request back to your origin storage. This cuts latency from hundreds of milliseconds to single digits.
For a file hosting system, the CDN is not just for static assets. You can cache public files, thumbnails, and compressed versions of larger files. Set cache control headers based on file type and expected access patterns. Profile pictures might have a long TTL, while user generated content shared in a live stream might need a shorter one. If the CDN does not have the file, it pulls from the next tier and caches the result for subsequent requests.
Tier 2: In-Memory Cache and Hot Storage
The second tier sits behind the CDN and handles files that are too large or too dynamic for edge caching. This tier uses an in-memory store like Redis or Memcached for metadata and small files, paired with a high performance local storage layer (NVMe SSDs on dedicated nodes) for larger hot files. Files that have been uploaded in the last few hours or that are being accessed frequently live here.
This tier is critical for write heavy workloads. When a user uploads a file, the application writes it to the hot storage tier first. A background job then replicates it to the cold tier. The user gets a success response immediately, even if the replication to archival storage takes a few seconds. This pattern is sometimes called write behind caching. It makes the upload feel instant while ensuring durability.
Tier 3: Object Storage and Blob Backend
The durable home for every file is the object storage tier. This is your S3 compatible bucket, Google Cloud Storage, or Azure Blob Storage. It stores the original, unmodified version of every file. This tier is designed for durability, not speed. Data is replicated across multiple geographic regions and can survive the loss of an entire data center.
Object storage is the source of truth. If the CDN cache clears or the hot storage node fails, the system retrieves the file from object storage and repopulates the upper tiers. Because object storage is relatively cheap per gigabyte, you can keep files here indefinitely. Use lifecycle policies to move older files to even cheaper archival tiers (like tape or cold cloud storage) after a set period.
Tier 4: Metadata and Index Database
File hosting is not just about storing bytes. You also need to know where files are, who owns them, what their permissions are, and when they were last accessed. That metadata lives in a separate database tier. Using a relational database (PostgreSQL) or a distributed key value store (DynamoDB) keeps metadata queries fast and isolated from blob storage operations.
The metadata tier is often the most overlooked part of a multi-tier architecture. If your storage is perfectly redundant but your metadata database goes down, no one can find their files. Replicate the metadata database across at least two regions, and use read replicas for API queries. This separation also makes it easier to run analytics on access patterns without impacting file delivery.
How to Design the Data Flow Between Tiers
The magic of a multi-tier architecture is in how data moves between layers. Here is a numbered process for handling a typical file read request:
- A user requests a file via your API. The API gateway first checks the CDN edge cache. If the file is present and fresh, the CDN serves it immediately. Request ends.
- If the CDN misses, the request goes to a load balancer that routes to an application server. The server checks the in-memory cache (Redis) for the file metadata and a small hot storage node for the blob.
- If the hot storage has the file, the server streams it to the user and signals the CDN to cache it for future requests. The user gets a fast response.
- If the hot storage also misses, the server fetches the metadata from the database to learn which object storage bucket and key hold the file. It then retrieves the blob directly from object storage.
- The server streams the file to the user, writes a copy to the hot storage tier for future hits, and tells the CDN to cache it. The object storage tier remains the durable source of truth.
This flow means that a single file can be served from three different tiers depending on access patterns. The system automatically promotes hot files to faster tiers and lets cold files stay in cheap storage.
Common Mistakes When Building Multi-Tier Systems
Even experienced teams make errors when layering storage tiers. The table below outlines the most frequent mistakes and how to avoid them.
| Mistake | Consequence | Better Approach |
|---|---|---|
| Using the same storage for hot and cold data | Hot data access slows down because cold data consumes IOPS | Separate hot (NVMe/SSD) and cold (object storage) tiers with automated migration policies |
| Not setting CDN cache invalidation rules | Users see stale files after updates | Use cache tags or surrogate keys to invalidate by file ID or user ID |
| Ignoring metadata database replication | A single database failure makes all files invisible | Run at least one read replica in a different region and use connection pooling |
| Forgetting to pre-warm the cache after a deployment | First requests after deploy hit object storage directly | Use a cache warming script that hits popular file endpoints after each deploy |
| Skipping rate limits between tiers | A traffic spike on the CDN cascades to object storage | Implement circuit breakers and fallback responses at each tier boundary |
Choosing the Right Storage Backend for Each Tier
Not all object storage is the same, and not all caching layers need the same hardware. For the hot storage tier, consider using a distributed file system like MinIO or a cluster of NVMe drives managed by your orchestration layer. MinIO is S3 compatible, so your application code does not need to change when moving between tiers. For the cold tier, standard S3 buckets with automatic tiering to glacier or deep archive classes work well.
The metadata database should be ACID compliant if you need strong consistency for file permissions and sharing. PostgreSQL with the pg_partman extension handles time series metadata well. For systems that prioritize availability over immediate consistency, DynamoDB or Cassandra are solid choices. The key is to keep the metadata database small and indexed. Store only pointers in the database, not file contents.
A useful pattern is to use a separate “staging” bucket for files that are still being uploaded. Once the upload completes, move the file to the permanent object storage bucket and update the metadata database. This prevents partial uploads from polluting your main storage and simplifies cleanup of abandoned uploads.
Monitoring and Failover Strategies
A multi-tier architecture is only as good as its monitoring. Each tier needs health checks, latency tracking, and automated failover. Here are the metrics that matter for each layer:
- CDN tier: cache hit ratio, origin response time, error rate by edge location
- Hot storage tier: disk IOPS, memory usage, replication lag
- Object storage tier: upload success rate, retrieval latency, bucket size growth
- Metadata tier: query response time, replication lag, connection pool saturation
Set up alerts for when any tier’s latency exceeds two standard deviations from its baseline. If the hot storage tier fails, the system should automatically route reads directly to object storage. The response will be slower, but the user will not see an error. This graceful degradation is the whole point of a multi-tier design.
For writes, use a write ahead log (WAL) or a message queue. When a user uploads a file, write the metadata to a queue first. A worker processes the queue and writes to the hot tier, then to object storage. If the worker crashes, the queue preserves the pending write. This pattern is used by systems like Apache Kafka or RabbitMQ in production file hosting pipelines.
“The most resilient file hosting systems are not the ones with the fastest storage. They are the ones that can fail gracefully. Each tier should be designed to fail independently, and the system should know how to route around the failure without dropping a single request.” — Senior Infrastructure Engineer, 2026
Tuning for Cost vs. Performance
A multi-tier architecture gives you fine grained control over cost. You can spend money on fast storage only for the files that need it. Here is a bulleted list of cost optimization strategies:
- Set TTLs on the CDN cache aggressively. Files that are accessed once and never again do not need to stay in the edge cache.
- Use different object storage classes. Store thumbnails and compressed previews on standard tier storage. Store original high resolution files on a cheaper archival tier.
- Automate file expiration. Delete or archive files that have not been accessed in 90 days. Notify users before deletion.
- Pool your hot storage nodes. Instead of dedicating NVMe storage per application, use a shared hot storage cluster that all services can access.
- Monitor your cache hit ratios. If your CDN hit ratio drops below 80%, review your cache control headers and file access patterns.
The goal is to spend more per gigabyte on the data that generates revenue (active user uploads, shared team files) and less on data that sits idle (old backups, archived projects). This is exactly how large scale SaaS platforms keep their storage bills manageable while maintaining high performance for active users.
Putting It All Together: A Sample Architecture
Imagine you are building the file hosting backend for a team collaboration SaaS. Your users upload documents, images, and video clips. Here is how the tiers stack up:
- CDN edge: Cloudflare serves all public file shares and team avatars. Cache hit rate targets 90%.
- Hot storage: A Kubernetes cluster with 12 nodes, each with 4 TB NVMe. Stores files accessed in the last 48 hours.
- Object storage: AWS S3 with automatic transition to S3 Glacier after 30 days. Stores all originals.
- Metadata database: PostgreSQL with two read replicas in different AWS regions. Stores file paths, owner IDs, permissions, and access timestamps.
- Queue: Redis Streams handles upload events. A worker replicates new files from hot storage to S3 in the background.
This setup can handle thousands of concurrent uploads and millions of reads per day. If the Kubernetes cluster loses a node, the system continues serving from S3 (slower but available). If the primary PostgreSQL instance fails, the read replicas promote to master. If Cloudflare has a regional outage, traffic routes to the next available edge.
For more detail on choosing between centralized and decentralized approaches, see our guide on how to choose between centralized and decentralized file hosting for your projects in 2026. And if you are evaluating specific providers, the article on how to choose a file hosting provider that scales with your SaaS growth covers the key criteria.
Final Thoughts on Designing for Uptime
Building a multi-tier file hosting architecture is not about adding complexity for its own sake. It is about giving your system room to breathe. When one part of the system struggles, the others pick up the slack. Your users never see a 503 error. Your team sleeps through the night without being paged.
Start with two tiers: object storage for durability and a CDN for speed. Add a hot storage layer when you notice that the CDN miss rate is climbing. Add a separate metadata database when your API queries start slowing down because of blob storage lookups. Each tier you add makes the system more resilient and more predictable.
The architecture described here is not theoretical. It is the same pattern used by Dropbox, Google Drive, and every major SaaS file hosting platform. They all started with a single bucket and grew into layers. You can too.